| Map > Data Science > Predicting the Future > Modeling > Classification > Large Language Model > Attention | |||||||||||||||||||||||||||
Attention |
|||||||||||||||||||||||||||
| In an LLM, attention allows each word (token) to decide which other words are important when understanding it. For example:. | |||||||||||||||||||||||||||
| "The cat sat on the mat because it was tired." | |||||||||||||||||||||||||||
| When processing "it", attention should give high importance to "cat", because "it" refers to the cat. | |||||||||||||||||||||||||||
|
The basic idea is: |
|||||||||||||||||||||||||||
| Query
→ What am I looking for? Key → What information do other tokens offer? Value → What information should I receive from them? |
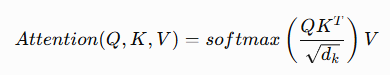
|||||||||||||||||||||||||||
| The core calculation is: | |||||||||||||||||||||||||||
| Start with simple sample data? | |||||||||||||||||||||||||||
| Let's use five words: | |||||||||||||||||||||||||||
|
"The cat sat there" |
|||||||||||||||||||||||||||
| We first represent each word as a vector. | |||||||||||||||||||||||||||
|
Python import numpy as np |
|||||||||||||||||||||||||||
| These are deliberately simple vectors. Real LLM embeddings have hundreds or thousands of dimensions. | |||||||||||||||||||||||||||
| Create Query, Key and Value | |||||||||||||||||||||||||||
| Attention transforms the input embeddings into three matrices: | |||||||||||||||||||||||||||
|
Python Q = X @ W_Q |
|||||||||||||||||||||||||||
| For our small example, let's use random weights: | |||||||||||||||||||||||||||
|
Python np.random.seed(42) |
|||||||||||||||||||||||||||
| Think of each token as asking: | |||||||||||||||||||||||||||
|
Query:
Key:
Value:
|
|||||||||||||||||||||||||||
| This separation is one of the most important concepts in Transformer architecture. Conceptually: | |||||||||||||||||||||||||||
|
|||||||||||||||||||||||||||
| Each number represents how strongly one token is related to another token. For example: | |||||||||||||||||||||||||||
|
score["cat"]["sat"] |
|||||||||||||||||||||||||||
| measures how strongly "cat" attends to "sat". | |||||||||||||||||||||||||||
| Scale the scores | |||||||||||||||||||||||||||
| Transformers divide the scores by: | |||||||||||||||||||||||||||
|
Python scaled_scores = scores /
np.sqrt(d_k) |
|||||||||||||||||||||||||||
| This prevents the numbers from becoming too large when the embedding dimension is large. | |||||||||||||||||||||||||||
| Apply Softmax | |||||||||||||||||||||||||||
| Now we convert the scores into probabilities. | |||||||||||||||||||||||||||
|
Python def softmax(x): |
|||||||||||||||||||||||||||
| We now have something like: | |||||||||||||||||||||||||||
|
|||||||||||||||||||||||||||
| The actual numbers will depend on the randomly initialized matrices. Notice that each row sums to 1. | |||||||||||||||||||||||||||
| [[0.0433943 0.11325699 0.17832943 0.66501928] [0.11283799 0.19335497 0.17931582 0.51449122] [0.43232588 0.16695836 0.25569743 0.14501833] [0.28463646 0.27860508 0.27294232 0.16381615]] |
|||||||||||||||||||||||||||
| Use the attention weights to combine Values | |||||||||||||||||||||||||||
| This is the final step: | |||||||||||||||||||||||||||
|
Python output = attention_weights @ V |
|||||||||||||||||||||||||||
| So the complete process is: | |||||||||||||||||||||||||||
|
|||||||||||||||||||||||||||
| Self-attention | |||||||||||||||||||||||||||
| Suppose we are processing the word: | |||||||||||||||||||||||||||
|
"cat" |
|||||||||||||||||||||||||||
| Its attention row might look like: | |||||||||||||||||||||||||||
|
The: 0.10 |
|||||||||||||||||||||||||||
| That means: | |||||||||||||||||||||||||||
|
Attention |
|||||||||||||||||||||||||||
| The representation of "cat" is therefore updated using information from the other tokens. This is why we call it self-attention, the tokens attend to other tokens within the same sequence. | |||||||||||||||||||||||||||
| The actual attention pattern is learned during training; we shouldn't hard-code these numbers. | |||||||||||||||||||||||||||
| Python code for complete Attention implementation. | |||||||||||||||||||||||||||